Monitored Into Blindness: The Paradox of Watching Everything and Seeing Nothing
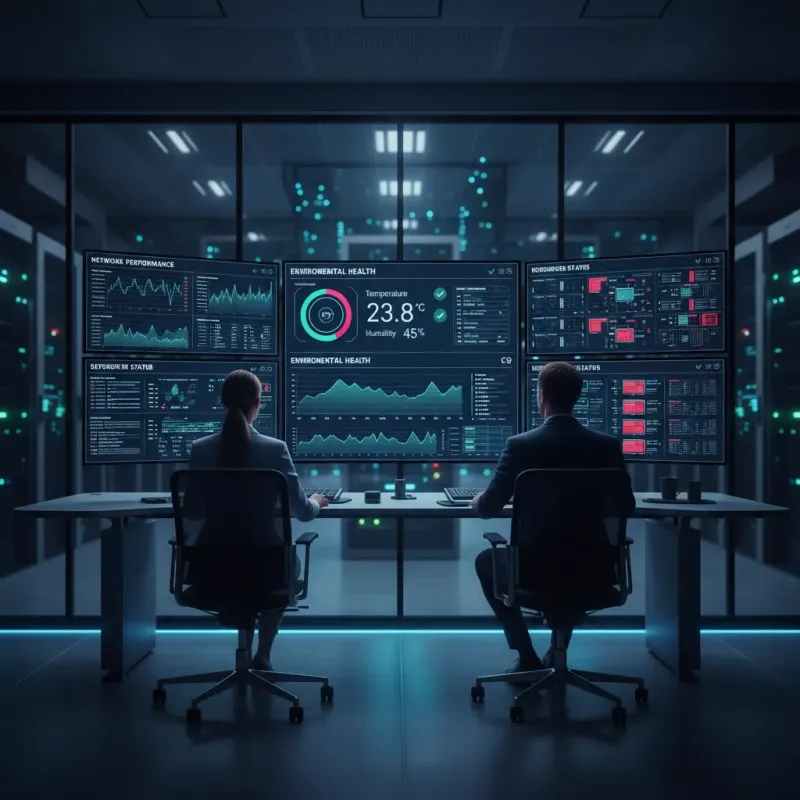
Photo: enterprise monitoring dashboard data center operations team, via www.techstar.com.pk
The Dashboard That Doesn't Tell You Anything
Walk into the operations center of a large US enterprise and you will often find something that looks impressively comprehensive: multiple screens, dozens of live metrics, color-coded thresholds, and a steady stream of alerts. The visual language of control is everywhere. What is frequently absent is actual understanding.
This is the visibility paradox — a condition in which the investment in monitoring infrastructure outpaces the organization's capacity to interpret what it is seeing. More data streams are added. More dashboards are built. More alerts are configured. And yet, when something goes genuinely wrong, the teams responsible for responding are often caught off guard, sifting through noise to find the signal that matters.
For enterprises that have spent heavily on observability platforms and monitoring tooling, this is an uncomfortable conclusion. But the evidence is difficult to ignore.
How Enterprises Arrive at This Condition
The path to monitored blindness is rarely the result of poor intentions. It is the product of reasonable decisions made in isolation, without sufficient regard for the cumulative effect.
A security team adds endpoint monitoring. An infrastructure team deploys a network performance tool. Application teams instrument their services with APM platforms. A compliance requirement triggers the addition of audit logging. Each decision is defensible on its own terms. Each tool generates data. And over time, the organization finds itself managing a sprawling observability ecosystem that no single team fully understands and that no single view can coherently represent.
The problem is not the volume of data. It is the absence of a governing question: what do we actually need to know, and how will we know when something important is happening?
Without that question answered at the organizational level, monitoring infrastructure tends to expand according to the path of least resistance — capturing everything that is easy to capture, rather than prioritizing what is operationally meaningful.
Alert Fatigue: The Hidden Cost of Over-Instrumentation
The most visible symptom of this condition is alert fatigue. When monitoring systems generate alerts at a rate that exceeds the team's capacity to evaluate them, the human response is predictable: thresholds get raised, notifications get silenced, and alerts get dismissed without investigation. The monitoring system continues to fire. The team continues to filter.
The danger is not that the system stops sending signals. It is that the team stops trusting them. In an environment where the majority of alerts are noise, the rational adaptation is to treat alerts as noise by default — which means that when a genuine signal arrives, it is likely to receive the same skeptical response as the hundreds of false positives that preceded it.
This dynamic has contributed to some of the most costly operational failures in enterprise technology. Post-incident analyses frequently reveal that the warning signs were present in the monitoring data. They simply were not visible against the background noise, or they did not trigger the right response because the team had learned to discount alerts from that particular system.
Fragmented Dashboards and the Illusion of Synthesis
A related problem is the fragmentation of monitoring data across tools and teams. When infrastructure metrics live in one platform, application performance data lives in another, business KPIs live in a third, and security events are tracked in a fourth, the organization has all the pieces but no coherent picture.
Leadership may review a dashboard that shows green across the board — because the dashboard is configured to surface only the metrics that have been pre-identified as important, and those metrics look fine. Meanwhile, a correlation between two data streams that would reveal an emerging problem goes unnoticed because no one is looking at both streams simultaneously, and no system has been configured to look for the relationship.
This is the deeper failure of fragmented observability: it optimizes for reporting rather than understanding. Each tool tells a story about its own domain. No tool tells the story of the whole.
Monitoring the Right Things: A Strategic Reorientation
Addressing this paradox requires a fundamental shift in how enterprises think about observability — from a collection of tools to a coherent strategy.
The starting point is not technology. It is clarity about what the organization is trying to protect and what failure actually looks like at the business level. From that foundation, monitoring can be designed to surface the signals that matter rather than everything that can be measured.
Signal-to-noise discipline. Enterprises that manage observability effectively treat alert volume as a health metric in its own right. When alert rates climb, that is treated as evidence of a misconfigured system, not as evidence of a more complex environment. Teams are empowered — and expected — to tune monitoring aggressively rather than simply adding more thresholds.
Cross-functional visibility design. Rather than allowing each team to build its own monitoring stack in isolation, leading enterprises establish shared observability frameworks that enable correlation across domains. Infrastructure, application, and business metrics are designed to be viewed together, not in parallel silos.
Outcome-oriented metrics. The most meaningful monitoring is tied to outcomes that have business significance — customer experience, transaction completion rates, service availability — rather than purely technical indicators that may or may not correlate with what customers actually experience.
Regular monitoring audits. Monitoring configurations that made sense two years ago may no longer reflect the current architecture or the current risk profile. Enterprises that treat their observability stack as a living system — subject to the same review and rationalization applied to other infrastructure — tend to maintain more coherent and actionable visibility over time.
Seeing Less, Understanding More
There is a counterintuitive discipline required here that runs against the instincts of most technology organizations: the willingness to monitor less in order to understand more. Reducing alert volume, consolidating dashboards, and deliberately limiting the scope of what is tracked can feel like a reduction in safety. In practice, it is often the opposite.
The goal of enterprise observability is not to capture every possible signal. It is to ensure that the signals that matter are visible, interpretable, and actionable by the people responsible for responding to them. That goal is not served by accumulation. It is served by design.
For enterprise leaders evaluating their current monitoring posture, the most important question is not how much they are watching. It is whether they would know — quickly, clearly, and without ambiguity — if something that genuinely mattered had gone wrong.